A 30,000,000,000 row join! And how we reduced runtime of a query by >99%
Last week we at Aampe faced a simple yet interesting scale problem when using BigQuery. The culprit: A simple inner join. We wrote a simple query that joins the users who are eligible to be messaged with their corresponding messages CMS table. The output needed: for each user, all messages that they are eligible to […]
How we handle messy data
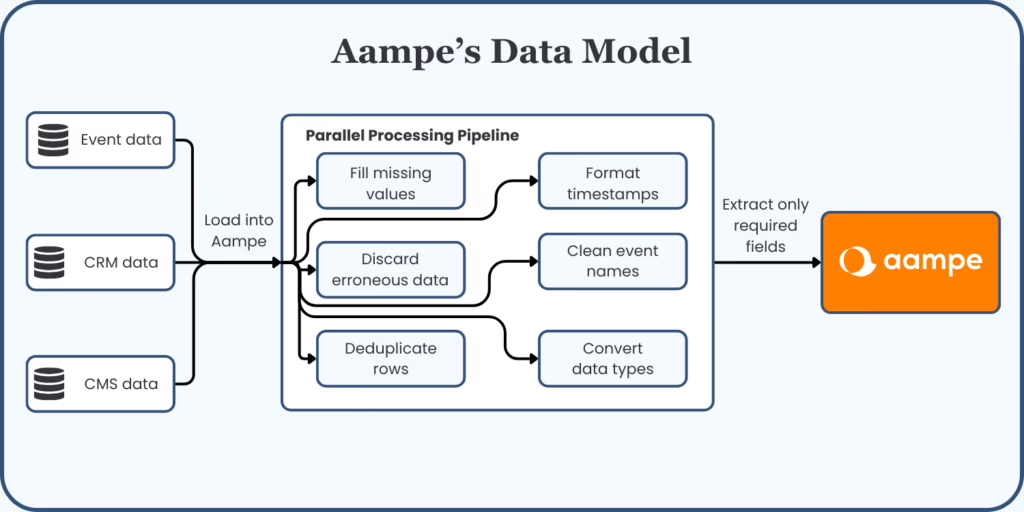
As our platform has to work with various data providers, CDPs, and many different companies with very different data lakes and schemas, it’s actually more common for us to encounter messy data than anything else. Here’s our approach to cleaning up this data so it can be usable and actionable: What is “messy” data? “Messy […]