The LLM Alignment problem
LLM “alignment” refers to reducing the gap between LLM output and user expectations. I came across a nice technical overview (LLMs from scratch) comparing the two main methods for LLM alignment: Reinforcement Learning from Human Feedback (RLHF) and Direct Preference Optimization (DPO). My conclusion: both methods show how talk about AI alignment is really missing […]
Message Catalogs on Aampe
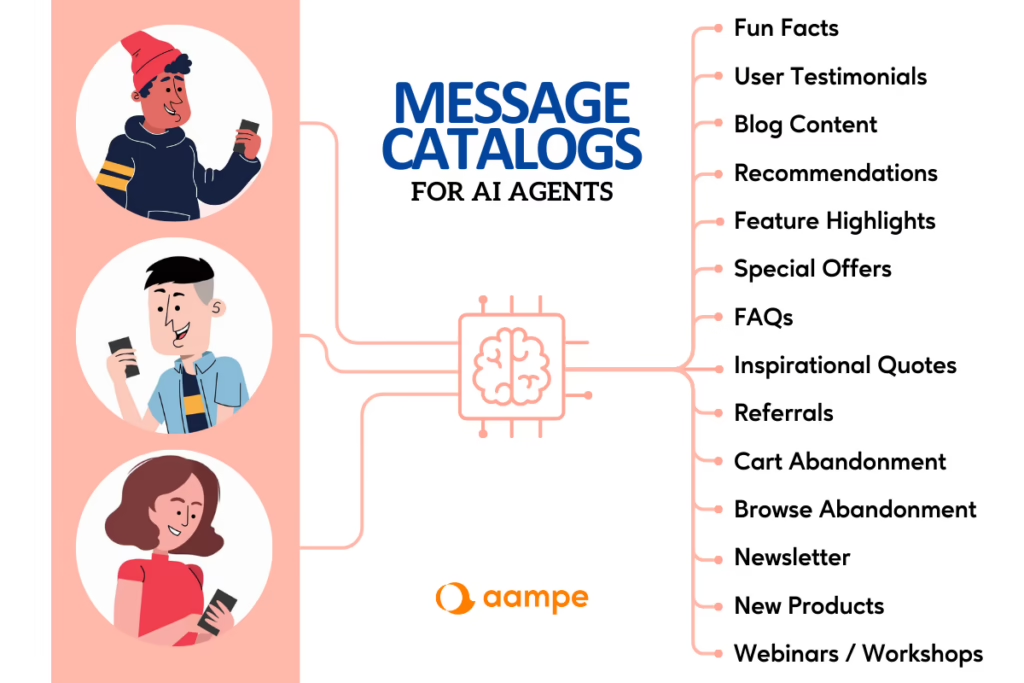
Traditional messaging campaigns, whether email, SMS, or push notifications, are designed to target specific user segments created based on arbitrary rules. Those rules are declared based on one’s intuition and limited understanding of their audience’s diverse preferences and needs. Moreover, teams have no choice but to rely heavily on industry benchmarks to predetermine the best […]
The Fluid Dynamics of Message Personalization
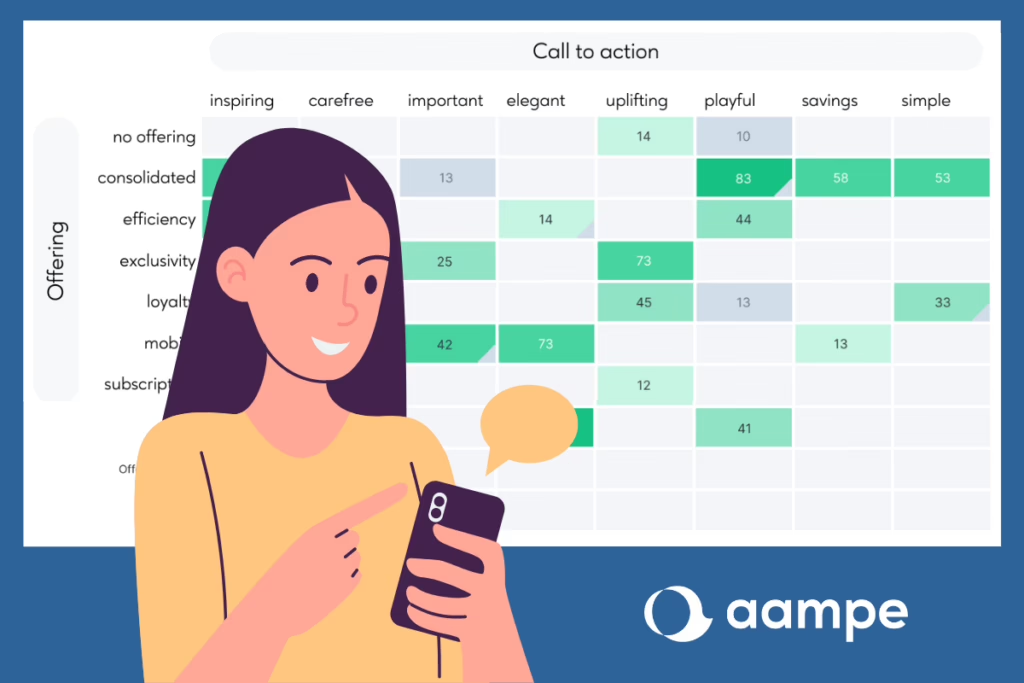
Over the weekend, I had some neighbors over for a barbecue. One of them works in computational fluid dynamics, and as we chatted about his work, something clicked with some refactoring we’ve conducted recently at Aampe. He explained that in his field, the cost (both in computational complexity and actual dollars) of observing real-world fluid […]